AI Slop: AI content is marked and it is losing
People are creating content more than ever before. Content creation on almost every channel we manage has roughly doubled in the last three years, websites, marketing copies and graphic design. It has not scaled reach, and it has not scaled engagement or conversions.
That gap is the story. There is now far more content competing for the same limited attention, and platforms and models have started sorting it. Not by quality, which is hard. By origin, which turns out to be easy.
We have been saying this was coming for a while. We no longer have to plan for it. The marking has shipped, the platforms are labelling, and our own figures show what it costs.
What is AI Slop?
In my terms, broadly: production with no thought behind it.
It is not “made with AI”. We use AI every day. Slop is what comes out when nobody made a decision before it went live, and it shows up in every discipline we work in.
In design, it is a poster carrying five million things when its only job is to stop a thumb on a fast-moving feed. In web, it is a site overloaded with information and no hierarchy, so everything shouts and nothing lands. In writing, it is copy that reads identically to every competitor’s and has no context for the specific market it is meant to be talking to.
The technical side is where it gets expensive, and this is the part clients never see coming. We have been handed five-page websites that are actually one page, loading new content with JavaScript. It looks slick. It is one enormous page as far as search engines are concerned, and it kills your SEO. We have asked AI to build plugins and been given code with serious security holes that would not scale past the first real load. Junk in, junk out, except the junk is now sitting on a live domain with your name on it.
And yes, there is slop in our own output. I doubt we have caught all of it. We are guilty of it too, and pretending otherwise would be its own kind of slop.
That is the real problem. It is too easy. The effort that used to sit between having an idea and publishing it was doing more work than anyone realised, and it has been removed.
The platforms are already sorting
We manage marketing for a handful of companies on LinkedIn. When we took these accounts over, the pattern was consistent: posts generated with AI performed worse than posts written by a person. We did not want to believe it on other people’s accounts, so we ran the same test on our own profile. Same result.
LinkedIn now lets users report AI slop directly in the feed. Reddit has updated its community guidelines to act against primarily AI-generated posts. Facebook labels AI content, and in our experience a labelled post performs worse than the same post written by a person.
YouTube went further and put it in writing. Creators are required to disclose when AI has been used to generate or significantly modify realistic content. Labels appear on the player or in the description. And this is the line worth reading twice: if a creator does not disclose it but YouTube’s systems detect it, the platform applies the label automatically, and creators cannot remove it where there is a high degree of confidence that the content was created with AI.
All of this means measurable things. Fewer views. Less dwell time. Less engagement. Fewer conversions.
Four platforms moving in the same direction, in the same window.
And now the models are marking it too
This is the part most people have not caught up on.
Anthropic has confirmed on its own support pages that Claude models launched from 2 August 2026 carry machine-readable marking. The text carries a built-in watermark that works by subtly skewing the words the model chooses, so that a pattern becomes detectable across enough content. Files and images carry provenance metadata signed to the C2PA standard.
This applies globally. There is no way to switch it off, not for you and not for the person paying for the subscription. Claude says it does not affect output quality, but it will not remove it. Prompt Gemini and you will be told the same thing. It watermarks its text too.
The driver is Article 50 of the EU AI Act, whose transparency obligations became applicable on 2 August 2026. The European Commission’s Code of Practice on Transparency of AI-Generated Content is the framework built to demonstrate compliance with those obligations, and by the end of July 2026 around 190 companies and organisations had signed it.
Read what that code actually covers, because the second half is for people like us. Section 1 places obligations on providers, requiring that AI output in audio, image, video and text be marked in a machine-readable format and detectable as artificially generated. Section 2 places obligations on deployers, requiring disclosure of deepfakes and of AI-generated text published to inform the public on matters of public interest, unless that content has been subject to human review and falls under editorial responsibility.
Human review and editorial responsibility. That exemption is a significant amount of work, and it describes exactly the workflow we have been arguing for over the past two years.
Note what this means for the design side too. Provenance metadata travels with the file. A generated hero image arrives at your web designer already carrying a trace of its origin. This is not a writing problem. It is a pattern problem, an averaging problem, and it runs from text to image to the design of every element on the page.
Why are they spending real money on this?
Compliance is the stated reason. It is not the only one.
Every one of these signatories has a model to train, and every one of them has the same problem: the open web is filling with synthetic text, and models trained on their own output degrade. Model degradation is expensive and very difficult to reverse. A reliable signal that says “a machine produced this” is exactly the filter you would build to keep your training data clean.
Think about that and the direction becomes obvious. People do not want to consume AI content. The AI does not want to be trained on AI content. Everyone now has their own AI product to protect. Reddit, LinkedIn and YouTube are no longer just blocking scrapers, they are managing slop inside their own platforms, because an average feed is a slowly dying product.
Google has signalled where it stands through E-E-A-T. Evidence in our own data suggests it is already a factor in ranking and citation rates.
What the top of the SERP actually looks like
We tested this rather than trusting it.
We took the top ten results for service industry queries in markets where SEO is genuinely competitive and everyone knows what they are doing, including New York and London. We ran those top-ranking pages through AI checkers. Seven of the ten came back as human writing.
That does not mean AI never touched them. It probably did. It means whatever the AI produced was then heavily edited by a person before it went live, to the point where the machine’s fingerprints were gone.
AI detectors are not reliable instruments. They produce false positives and false negatives, and we would not make a business decision on a single result. The signal here is the consistency of the trend across ten competitive results, not the accuracy of any one score.
The pattern lines up with everything else on this page. At the top of hard markets, humans are still driving.
E-E-A-T is the reason, and AI cannot fake it
Google has been clear for years that it wants experience, expertise, authority and trust. We have written about this many times, because it is the framework that explains almost everything else.
A language model on its own cannot produce real E-E-A-T. It produces the average of what it has already seen. Experience means having actually done the thing. Expertise means knowing which of the plausible answers is the right one in this specific case. Neither is available to a system whose function is to predict the most likely next word.
Give it real industry experience and it becomes a useful writing tool. Ask it to supply the experience itself and you get exactly what everyone else in your industry is publishing, worded slightly differently.
That is the whole mechanism. This is not a conspiracy against AI. It is an average, applied to a ranking system explicitly designed to reward the opposite.
What our own numbers say
We stopped guessing and measured it. Four separate tests, all on sites we control or manage.
| What we tested | Finding |
|---|---|
| Well-ranking existing articles that we then edited with AI | Performance fell 78% of the time, measured by views, dwell time, engagement and conversions |
| 103 articles written purely by humans before 2023, versus new AI content | 72% higher citation rate |
| 57 newly written articles written without AI, versus new AI content | 63% higher citation rate |
| 13 pairs of pages on our own site, a non-AI and an AI-generated version, running three months each | 16% more dwell time, 23% more conversion actions per session and 18% lower bounce rate on the non-AI version |
Citation rate here means how often content is retrieved and cited by AI search tools, measured with Semrush’s AI Visibility tool, which shows which prompts trigger AI citations.
A caveat on the 103 pre-2023 posts. Those pages are older, and older pages carry backlinks and authority that newer pages have not had time to earn. Part of that 72% is age, not authorship. Which is exactly why the second test matters more: 57 recently written articles, competing on an even footing with AI content, still came out 63% ahead.
The A/B pairs are the ones that should worry anyone running a content programme, because dwell time, bounce and conversion actions per session have nothing to do with domain authority. Same site. Same traffic sources. Same three month window. The only variable was how it was written.
The indexing problem nobody warns you about
Our hosting team noticed something separate, and it fits.
When clients generate a full website with AI and put it live, some of those sites do not get indexed by Google at all.
Google has never published an official indexing schedule, and many factors feed into it. What we know from doing this for a decade is that content Google likes tends to get indexed in about two weeks, sometimes faster. On the AI-generated sites we host where indexing did happen, the average was closer to two months.
Not all of them. But enough for us to raise it before a client goes down that road.
If you are wondering why the site you built in an afternoon is not producing enquiries, indexing is the first place to look. The rest of the reasons sit on our AI entity and digital authority optimisation page.
We asked ten people why they stopped reading
The numbers tell you what happened. They do not tell you why. So we interviewed ten people and deliberately picked a spread: five of our own clients, two members of our internal team, and three members of the public with no technical background. Developers and non-developers, clients and business people.
Ten is a small sample and we are not presenting it as research. It was the consistency of the answers that was worth noting.
- Seven of the ten said they do not avoid content because it is AI. They avoid it because it is generic and unoriginal.
- Three said that as soon as they spotted a tell, a phrase like “in conclusion” or an obviously generated image, they questioned whether they could trust what they were reading, and left.
- Six said it made them question the brand behind the content, not just the article.
That first finding runs against the popular version of this argument. People are not policing ideology. They are bored. The rejection is not about the technology. It is about the average.
That is a much harder problem to solve, because averaging is what the tool is designed to do.
Seven clients. Seven industries. One website.
Here is the part that makes the averaging argument impossible to dismiss, because you can see it rather than measure it.
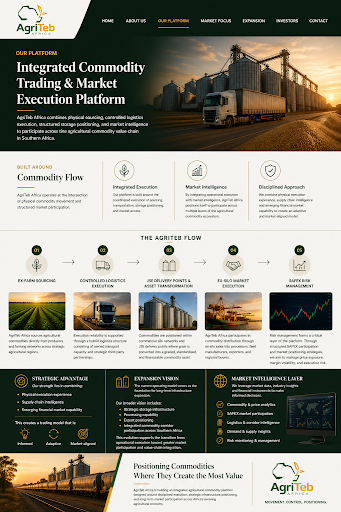
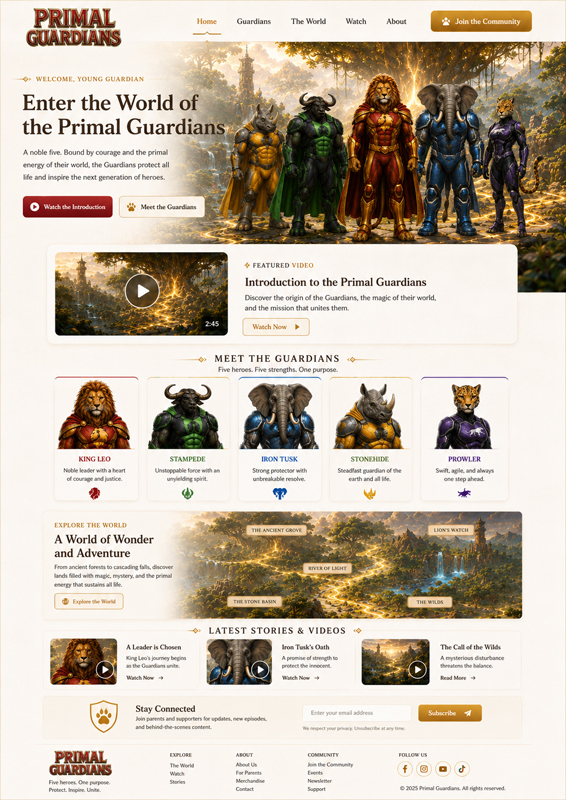
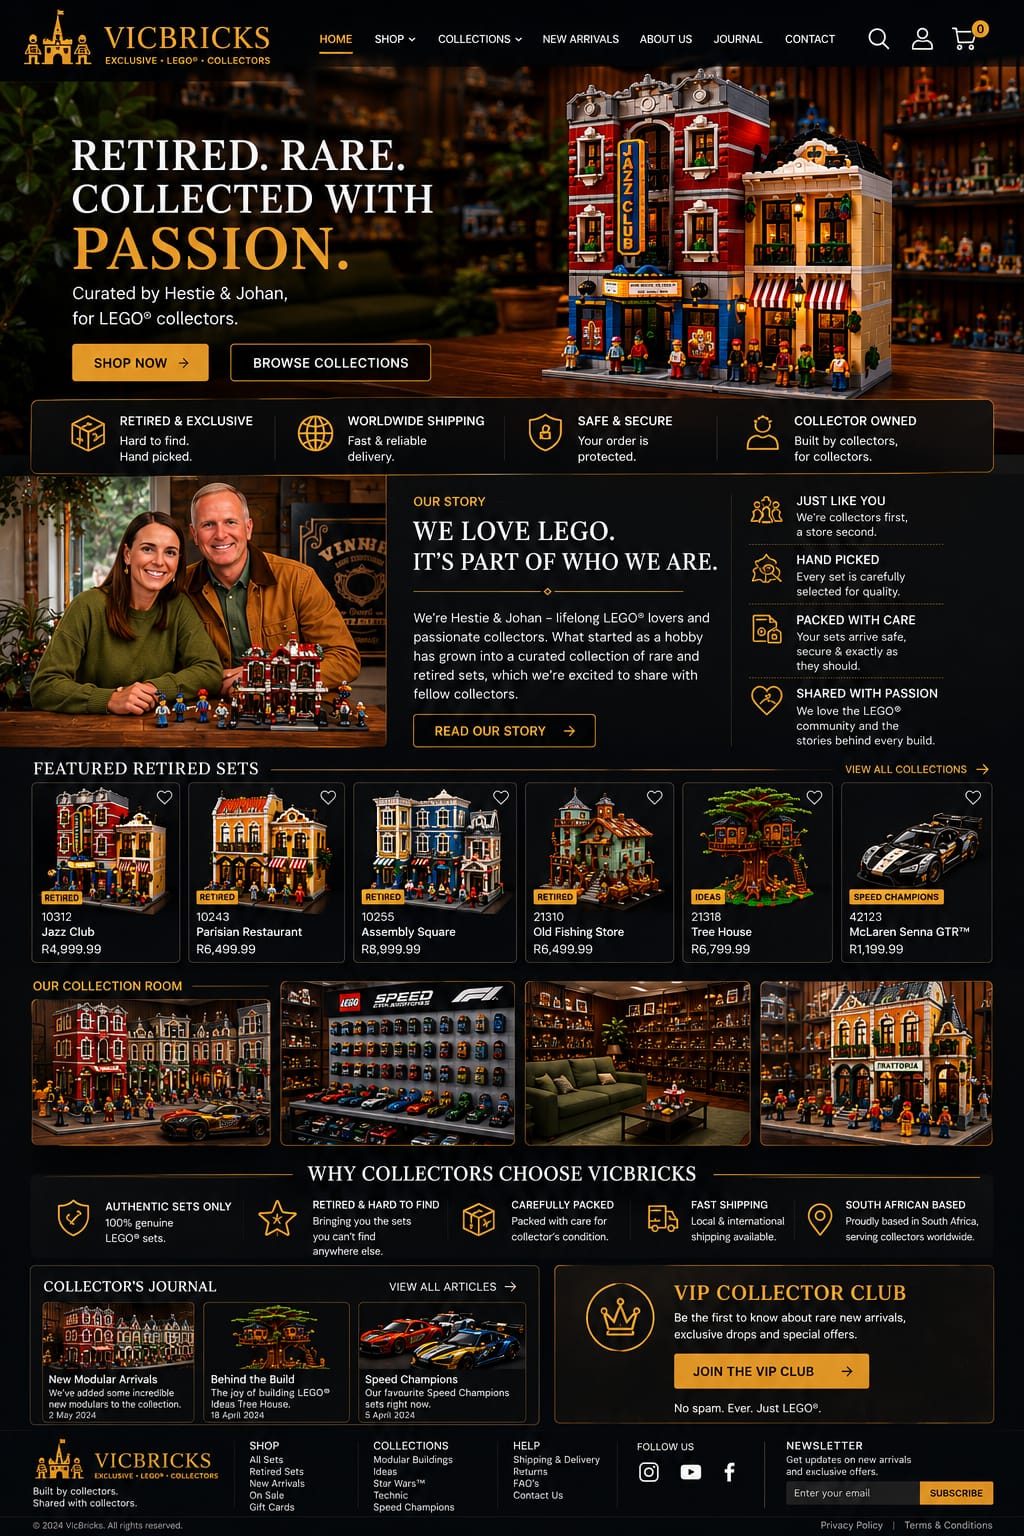
Clients have recently started sending us AI-generated mockups, this is AI Slop in all its glory, they want their site to look like. No briefs. Finished visuals, made in an afternoon, arriving as images. We now have seven, from seven different companies, in seven unrelated sectors.
They look alike.
Not alike in the way two good sites in the same sector are alike. The same. Same dark background with an accent colour running through everything. Same gradient over an industrial stock photo. Same centred heading in capitals with a small decorative rule either side. Same row of four icons with two words under each. Same three-column card grid, then another three-column card grid, then a stat strip, then another card grid.
An agricultural produce retailer and a LEGO collectibles store arrived at the same layout. That should not be possible. It happens because the tool does exactly what it was built to do: produce the average of every website it has ever seen, and the average of every website is a dark hero, a row of icons and three cards.
Now look at them the way a designer would, or for that matter the way a client should.
There is no hierarchy. Every strip on the page carries the same visual weight, so nothing is emphasised and the eye has nowhere to rest. There are six or seven calls to action of equal importance, so there is no primary action. The body text is far too small against enormous section headings. Every section is symmetrical, so nothing stands out by contrast. And the whole page tries to say everything the company does at once, above and below the fold, without a single editorial decision about what actually matters.
It looks like a poster you made in grade six. One sheet, the whole project had to fit, so you crammed it all in and drew borders around the gaps.
This is not a style problem you fix with a better colour palette. This is what happens when nobody has made a decision. Design is a series of decisions about what to leave out and what the visitor should do next. A template averaged from thousands of layouts has no idea what your particular client should do next, because it does not know your client. So it includes everything, weights everything equally, and hands you a page that converts nobody.
The point that matters for this article: it is the same failure as the copy. Text, images, layout, all from the same averaging process, all arriving at the same place. When we say the averaging problem runs past writing into design, that is what we mean, and we have seven pictures of it.
Same skeleton, better manners
Not every generated design arrives a mess. Some look perfectly professional, and those are more dangerous, because there is nothing obvious to object to.
We were recently sent a plumbing mockup that was tidy. Sensible order, clear heading, one primary and one secondary button, a proper emphasis break in the middle. Scroll it quickly and you would call it a decent local service website.
Then put it next to the others and count the sections. Hero with a split image. Band of four icons. About block with three ticks. Card grid. Two-column split. Call to action band. Six-item “why choose us” grid. Three-step process. Service areas section. Two-column problem list. Three testimonials. FAQ accordion. Three blog cards. Call to action at the foot of the page.
Same skeleton as the commodities trader and the LEGO store. Different colour, different industry, more padding, better manners. Identical bones.
Which makes it the more useful example, because you cannot write this one off as poor execution. It survives on being well executed. This is what the average looks like when it is sharp.
Then open it on a phone
Every one of those decisions is a desktop decision, and nobody generating them is checking the other view, because they are looking at an image of a desktop page.
Stack it responsively and the strip of four icons becomes four rows of a small icon and two words, most of a screen saying nothing. The eight-card service grid becomes eight full-width cards in a column. The six-item “why choose us” grid stacks into six more. The three-step process, three more. The two-column problem list, six more rows. Then three testimonials, then the FAQ, then three blog posts. The visitor scrolls through the better part of twenty near-identical blue and white blocks to reach the end of a page they never asked to read.
The images make it worse, not just longer. That page carries a generated hero, a generated team photo, several generated shots of a plumber at work, and a decorative card that means nothing at 390 pixels wide. All of it still has to load. On a phone on mobile data, that is your Largest Contentful Paint gone, on the exact device the customer is holding.
And think about who that customer is. Someone with a burst pipe, standing in water, on their phone, wanting one thing. The page offers them a call button in the header, a hero button, an emergency button, a call button in a mid-page band and two more in the footer. Six ways to do the one thing they came for, none of them dominant, spread across a scroll that takes a minute to get through.
A designer makes this page shorter on mobile, not longer. Cuts the service grid to the four that actually sell, drops the decorative card, keeps a sticky call button and kills the other five. Those are decisions about a specific customer at a specific moment. The model has no view of any of it, because it does not know who is standing in the water.
And then there is the part that is simply made up
The testimonials on that page are invented. Three quotes, three plausible names, three job titles, no actual clients. The star rating cites a number of satisfied customers nobody has counted. The team photograph is generated, so the trust signal is a picture of people who do not exist. The phone number in the emergency banner and footer is a placeholder that would have gone live. One of the service area buttons says “Your Area”.
That is the E-E-A-T argument in a single page. The model knows a converting local service site has testimonials, a rating, a team photo and contact details, so it produces the shape of all four. It cannot produce the substance of any of them, because substance requires having done the work. So it fakes it.
That is no longer just a conversion problem. Publishing fabricated reviews and a rating nobody earned is a consumer protection issue, and it sits on the client’s domain under the client’s name.
The day I stopped using eyebrows
I was designing a website last week and I put an eyebrow above a heading. Small uppercase label, sitting there above the H2, the way it does on every second website built in the last decade.
Then I stopped and looked at it properly. What does this thing actually do? What was it doing before AI? I could not tell you. I do not think it was doing much. It is a leftover from editorial print, where a kicker told you which section a story belonged to. On a landing page it mostly gives you a smaller piece of text above a bigger piece of text saying roughly the same thing.
We use them all the time. I have put them on a lot of sites. But every AI builder now emits them on every section by default, because that is the pattern it learned, and a device with no real job has become the visual signature of generated design. I deleted it. Not because it looked bad. Because it looked like AI.
That is the part worth sitting with. The design was fine. I rejected it anyway.
Recognition now arrives before judgement
This is the shift, and it is not really about eyebrows. It is about the order things happen in.
You look at a page. You recognise it as generated. Distaste arrives. Only then do you get around to assessing whether it is any good, and by that point the assessment does not matter, because you have already decided. Recognition has jumped the queue and evaluation never gets a vote.
Designers and writers have started building around this. We are steering away from patterns that read as generated even when those patterns may or may not work, and that is a strange line to walk. Some of these are legitimate design devices with decades behind them. They are being retired anyway, because association has overtaken function.
That is what AI fatigue looks like from the production side. Not people refusing to use the tools. People carefully making sure the output does not look like it came from them.
Three tiers, and only one of them decides it
There are three separate objections running at once, and they get lumped together, which weakens all of them.
- Creators object on rights and consent. Real, but self-interested, so people discount it.
- Practitioners object because it does not perform. Harder to dismiss, because it is a numbers argument and not a moral one. That is the case the figures above make.
- Consumers are simply tired of it. Nobody is paying them to feel that way, which is what our interviews turned up without us going looking for it.
The third tier is the one that decides everything, and almost nobody has priced it in. Consumer fatigue with Facebook took the better part of a decade to arrive. AI has managed it in about three years.
The reason is the thing everybody treats as the benefit. Volume. The speed that makes generated content attractive to produce is the same speed that exhausts the audience consuming it. It moves fast in both directions.
The recognition arms race
The obvious counter is that AI will get better and stop being detectable.
It will get better. So will we, and faster, because our side of it costs nothing. Nobody trains for this. It happens by exposure. Every generated thing you see sharpens the filter on the next one, and there is no upper limit on how many you are going to see. Detection improves for free while concealment has to be paid for.
That asymmetry is why this does not resolve itself.
The doors are closing on the supply side
The other pressure is on input, and it undercuts the idea that models simply keep improving.
Google did not crawl its way to Reddit’s archive. In February 2024 it signed a licensing deal worth roughly $60 million a year for access to it. You pay for something when you have run out of it. Reddit is now reportedly weighing whether to renew, with AI Overviews having cut the referral traffic publishers depend on.
The irony does a lot of work there. The people producing that human-written material on Reddit are the same people whose sites were stripped of traffic by AI summaries. They were not asked first. They were taken from again, and then asked. The answer was no.
I have been on Reddit a long time. Entire communities have formed around banning generated content outright, and inside the ones that have not, it is the heaviest contributors who are leaving. Those are the users who make the archive worth $60 million in the first place, the power users are leaving becase they understand AI will trin on their thoughts and while they were happy to share it with a fellow human echange of ideas, they arent .
Adobe learned the same lesson faster. Its June 2024 terms of use update read as though it granted the company broad rights over user content. The backlash was immediate, subscribers threatened to cancel, and Adobe rewrote the terms within three weeks, stating explicitly that users own their content and that it would not be used to train generative AI outside Adobe Stock submissions. A company that size does not reverse course in three weeks over a small problem.
Content owners are shutting the doors. The material that made these models good is getting harder to reach, and the material replacing it is increasingly generated. That is the degradation problem from the other end.
Average is a slow death
We live in the age of personalisation. Everything a consumer touches, from their banking app to their streaming service to the ads in their feed, is tailored to them. And in the middle of all that, an entire industry has started handing graphic design, web design, copywriting and campaign strategy to a machine whose defining characteristic is that it produces the average of everything it has ever seen.
Any brand that has been around long enough knows what the average does. It does not kill you on a Tuesday. It erodes you. Nobody chooses you, nobody remembers you, and the enquiries dry up over eighteen months without ever showing up as a single identifiable cause.
Gen Z wants expertise and personality. Gen X wants it. Boomers want it. That has been at the heart of good marketing for at least a decade and nothing in the current toolset changes it. If anything, the tools make real personality rarer, and therefore worth more.
We are not anti-AI
We use it every day. We build with it. The argument is not that it should be avoided.
The argument is about who is driving.
Giving AI to an untrained person is like handing them an F1 car. Plenty of people could get one moving. Most would drive it slower than a normal car and far more dangerously, and none would get near what a professional would do with the same machine. The machine is not the variable. The driver is.
Used by someone who knows what a page is supposed to do, AI is a real accelerator. Used as a replacement for knowledge, it produces exactly the average result that platforms label, models score and readers skip.
Where this goes next
The tipping point is no longer a prediction. The infrastructure is live.
Providers mark output at generation. Platforms label it and, in YouTube’s case, apply labels automatically whether the creator discloses or not. Regulators have a code of practice with 190 signatories. And every one of those companies has its own model to protect from degradation, which means none of them have any incentive to reverse.
What follows is simple. As the volume of generated content rises, audiences get better at spotting it, not worse. Consumers are already learning, and telling us so in interviews. Businesses will follow the numbers, as they always do. The hype will move to whatever produces results at a defensible cost.
When that happens, writers, designers and strategists who can produce something that is not average become more valuable than they were before any of this started. Not less. That is not a prediction we are hoping for. It is what our own data, platform policy and the top of the SERP already show.
We built the agency around that. Our work is still done by people who have been doing it for years, with AI in the toolbox and away from the steering wheel.
If you want the version that applies to construction sites, we have written it under web design in East London . The visibility side of search is on our AI entity and digital authority optimization page .
Sources
- How Claude Brands AI-Generated Content, Anthropic
- Code of Practice on Transparency of AI-Generated Content, European Commission
- The slop button of LinkedIn’s AI, Gary Monro
- How YouTube Works: AI
Frequently asked questions
Is AI content ranked on Google? It can be. Google’s stated position is that it rewards useful content regardless of how it was produced. Our own data suggests the practical result is different, particularly on indexing speed and how often content is cited by AI search tools. When we ran the top ten results for competitive service queries through AI checkers, seven came back as human writing.
Is AI content penalised? Not in the sense of a formal penalty. What we see is softer and more damaging: slower indexing, lower citation rates, shorter dwell times and fewer conversion actions. The effect is the same whatever you call it.
Can AI content be detected? Increasingly, and not by guesswork. Text from newer models carries an embedded watermark, and generated images and files carry signed provenance metadata. Detection tools that infer from writing style are unreliable. Model-embedded watermarking applied at the moment of generation is a different matter entirely.
Does the watermark disappear if I edit the text? Anthropic’s guidance is that heavy editing, paraphrasing or translation may leave no detectable mark, and short passages may not carry one. A light reread will not remove it. A genuine human rewrite is another matter.
Does a detected watermark mean the content was written by AI? No, and this is where it gets unfair. The mark appears on text produced by a model, including text where a person supplied the substance and the model only edited or translated it. It is a weak positive signal, not proof of authorship.
Should we disclose the use of AI in our marketing content? Under the EU Code of Practice, deployers must disclose AI-generated text published to inform the public on matters of public interest, with an exemption where the content has undergone human review and falls under editorial responsibility. Take advice on your own obligations, but the direction is clear: human oversight is what keeps you on the right side of it.
Can I just generate my website design with AI and send it to a developer? You can, and clients do. What arrives is almost always the same layout regardless of industry: dark hero, row of icons, three cards, repeated. It looks finished, and there is no hierarchy, no primary action and no decisions behind it. It is useful as a mood board. It is not a design.
My AI-generated design looks good. Why would it not work? Because you are looking at an image of a desktop page. Stacked on a phone, those eight-card grids and four-icon strips become twenty near-identical blocks for the visitor to scroll past, with generated images loading on mobile data along the way. Mobile design is a set of decisions about what to remove. Generation adds.
So should we stop using AI entirely? No. Use it where it is good: research, structure, first drafts to react to, repetitive production work. Do not use it as a replacement for knowledge, because that is the version the platforms label, the models score down and the readers skip.





0 Comments